Latency Benchmarking Methodology for Search API Infrastructure
Reliable API latency benchmarks must isolate network costs and measure accuracy alongside speed.
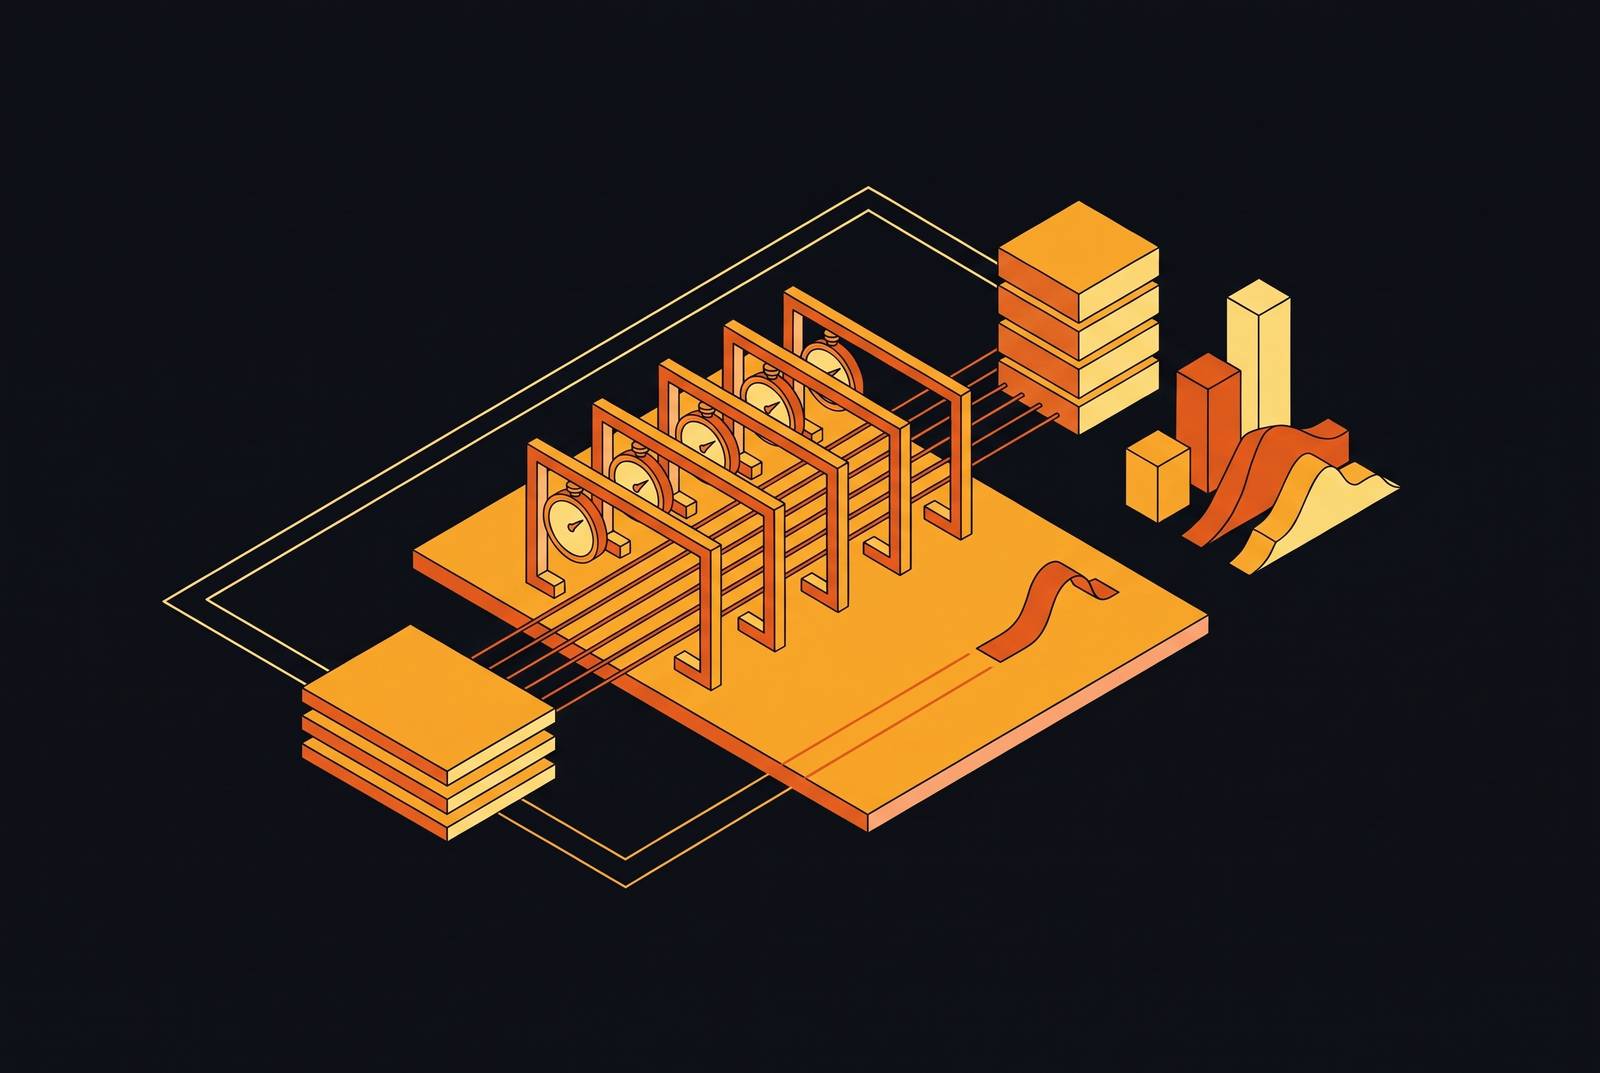
Search API latency benchmarking is useful only when it measures the conditions under which retrieved information helps an agent complete its task. That requires more than timing responses. A trustworthy methodology isolates network costs, counts failures, fixes the query set, measures freshness separately, and evaluates accuracy together with latency. The aim is to identify infrastructure that delivers usable answers within a real workflow’s time budget.
Why latency benchmarks for search APIs so often mislead
The dominant failure in search API benchmarking is measurement design. A team can collect precise timings and still answer the wrong question because its test does not resemble the conditions under which the API will run. Precision cannot repair a poorly defined test. A median measured against a local stub, for example, says little about a production request that crosses a network.
The more consequential mistake is to treat response time as a proxy for task success. What has an agent gained if a quick response contains weak, stale, or off-topic results? The request has finished, but the task has not. A benchmark that rewards that response teaches engineers to select for speed without establishing whether the output is useful.
What a latency number actually measures — and what it silently excludes
A search API request passes through distinct stages, including query encoding, index retrieval, reranking, and network transit. Each contributes to elapsed time, but they do not share the same optimization lever. Encoding time describes the preparation of the query, while retrieval time describes the index search. End-to-end round-trip time includes the network path as well. Without that boundary, two measurements labeled “latency” may describe different operations.
Network I/O is often the dominant production cost. A local FAISS search reporting 5 ms is not equivalent to a request sent over the network to a cloud vector database, and reranking adds further work. Isolated compute timings can explain part of a request without predicting the time an agent waits for its response.
A system may encode many queries quickly as a batch while a single query still waits. Thread contention, batch processing overhead, and model initialization also make timings on a development machine differ from how the system runs in production. The test therefore needs to measure single-query latency under realistic load and state which stages are timed and where each request starts and ends.
Why tail latency and timeout handling must be counted, not smoothed away
A median describes the middle of a distribution. A fast median can coexist with a slow p99, leaving agents exposed to unpredictable delays. Timeouts make the gap harder to interpret. Two providers with identical medians are operationally different if one times out on some requests and the other does not.
For benchmark authors, the practical requirement is to calculate percentiles from an explicitly identified successful sample and publish the failure count separately. Retries belong in the latency budget, even when they sit outside the successful-request distribution. Their cost reaches the agent’s wall-clock time. Excluding them without disclosure is a consequential reporting choice.
Concurrency and warmup also need explicit treatment. A single-threaded test against an idle API does not reproduce production contention, including thread contention and GIL blocking. The protocol should specify how many initial iterations are discarded for model initialization and CPU cache warmup. Publishing p95 and p99 with those conditions lets readers tell whether performance holds up or the run went unusually well.
How to build the query set that makes results comparable across providers
Openbenchmarks fixes its factual-lookup questions and answers before any provider runs. Each answer is a single verifiable value pinned to an official wire or newsroom URL. Its protocol runs 300 company-news questions per provider and checks whether the same answering model can get the correct value from the returned results. The target cannot move between provider runs.
The query type also defines the test’s scope. The September 2026 fastest-search board uses company-news factual lookups, with one search per question and a small, fixed limit on how many results come back. Such a test does not establish performance for every search workload. Equally, simple keyword lookups cannot stand in for natural-language agentic queries merely because both use a search endpoint.
To preserve comparability, the benchmark author must log query text, engine, country, language, concurrency, client region, timeout policy, retries, and cache state. A default-country request is not equivalent to a localized one. If cache state cannot be controlled or exposed, that limitation must remain visible. Holding the answering model constant then prevents differences in answer generation from becoming a confound in the retrieval comparison.
Separating freshness from speed — why they require different measurements
Response time measures how long retrieval took, while freshness concerns which version of the information came back. These properties are independent. A quick API can return a snapshot from hours ago, while a slower one returns the current page. Even a recently published source does not prove that the API retrieved that version on the measured attempt.
This distinction becomes operational when agents act on retrieved information. A financial agent working from yesterday’s positions may generate trades that are already invalid. Stale information can also cause problems when decisions affect inventory or customer experience. For production agents that must act quickly, the freshness target is sub-second to low-single-digit seconds, because delays beyond several seconds can lead to decisions that are wrong enough to matter.
What evidence would establish that the returned information was current? The benchmark should compare a reviewed source version with the retrieved version and retain the retrieval timestamp, content hash, and source publication or update timestamp. A SERP snippet date cannot establish that relationship on its own. Freshness therefore needs a separate measurement and evidence chain, rather than an inference from response speed or a claim of “real-time” retrieval.
Why accuracy cannot be a separate column — it is part of the latency budget
Accuracy and latency can have separate columns, but teams need to weigh them together when making a choice. Correct answers reduce retry calls and follow-up searches, which also reduces total token spend. Raw response speed captures only part of that cost.
Openbenchmarks makes the trade-off explicit in its factual-lookup board. It states that “the most accurate configuration is rarely the fastest or the cheapest, so each is reported in its own column”. Providers differ widely in accuracy on the same 300 questions. Reading those columns together exposes the choice that a speed-only ranking conceals.
The strongest objection is that accuracy depends on both the answering model and retrieval. That is true, but it does not justify removing accuracy from the test. Applying one fixed answering model uniformly makes retrieval quality the variable being compared within that setup. Multi-agent runs sharpen the consequence because weak results force additional calls across the loop. A defensible infrastructure decision therefore requires joint accuracy-and-latency reporting under the same answering model.
What a correctly assembled benchmark result looks like in practice
For a result to be valid, the rows of provider configurations must use the same questions, answering model, scoring judge, and fixed ground truth. Accuracy, average latency, median latency, and cost per thousand queries appear together. The shared conditions give the columns their meaning. Without them, a polished table may compare different tasks.
The fastest configuration is not necessarily the most accurate, and the most accurate is not necessarily the cheapest. An engineering team can interpret those differences against its task requirements only if the benchmark preserves their common basis. Failure reporting and tail measurements then show what the central timings leave out.
The factual-lookup board also illustrates why auditability needs precise description. Its runner is available in a public repository, and a 100-question public subset is on Hugging Face. The scored 300-question set, however, is locked and private. Readers can inspect the runner, scoring logic, provider configurations, and public subset, but cannot independently inspect the entire scored question set. That boundary belongs in the interpretation of the result.
How to run the same test against your own production traffic
For a team applying this methodology, the protocol begins by fixing the query set, ground truth, client region, concurrency model, and cache policy before provider runs. Queries should reflect the actual production distribution. Country, language, and result count must stay the same across requests, and each raw response should be saved. These controls establish what a later difference can reasonably mean.
Every attempt needs an audit record. That record should include the query, engine, requested country and language, concurrency, client region, timeout, retries, cache policy, HTTP and business status, expected fields, and usable-result decision. Retry timings should be reported separately unless the measurement is explicitly labeled complete-workflow time. Freshness records should retain the reviewed and retrieved versions with their timestamp and content-hash evidence.
For microbenchmarks, use time.perf_counter(), run a hundred or more iterations, and discard a specified number of initial warmup runs. Calculate percentiles from the sample identified as successful and publish failures beside them. These steps require a controlled harness. When a team uses the method on its actual query distribution, it has more to base its choice on than a third-party leaderboard alone.
Where compliance and privacy sit in the benchmark decision — and when they come first
In a regulated context, performance is not the first gate. A provider must pass compliance review to be a choice the team can use, even if its benchmark results are strong. Search APIs retrieving content for agents raise GDPR data-processor obligations and EU AI Act input-data questions under Article 3(34). Those roles set what the enterprise must audit before it compares response times.
The evaluation needs explicit requirements for zero data retention after request completion and a signed Data Processing Agreement under GDPR. It also needs data residency or Bring Your Own Cloud arrangements so queries remain within the customer’s VPC, plus SOC 2 Type II supported by an actual audit report. Policy language alone is insufficient. The assessment must establish where processing runs, what it can reach, and where query data physically goes.
That review also extends to prompt injection through retrieved content, API logging of queries, and third-party SaaS integrations handling query data. Colorado’s automated decision-making law and California’s ADMT rules both trigger compliance obligations on January 1, 2027. For affected teams, these requirements constrain the evaluation sequence.
What agentic infrastructure demands that static latency benchmarks cannot capture
A static benchmark measures a point-in-time API call, while an agent completes a sequence of calls. Task success depends on the sequence’s cumulative latency and accuracy. The unit of evaluation must therefore expand. Per-call measurements show how long each call takes, but more is needed to tell whether the full run fits the agent’s wall-clock budget.
Anthropic’s Model Context Protocol, or MCP, adds another boundary to that measurement. Agents find and query data sources through structured exchanges governed by a protocol, so timing only the HTTP response leaves out protocol overhead. The same distinction between component time and workflow time applies here, but across a broader interaction.
Domain-specific accuracy creates a further requirement. FORCE-Bench, FrontierFinance, BigFinanceBench, Hedge-Bench, FinResearchBench II, and Fin-RATE were all published in 2026, reflecting the development of finance-focused evaluation. General search tests leave out some of what financial agents need when they work with cited, source-reconciled data. Fixed questions, joint accuracy-and-latency measurement, explicit failures, and separate freshness evidence provide the baseline for those extensions. A harness that follows those rules can grow with the workload, without needing to be rebuilt when a single-call ranking no longer tells a team what it needs to know.