Hallucination Reduction in LLMs Through Search Grounding
Grounding LLMs with search evidence reduces hallucination through system design, not model size.
Search grounding reduces LLM hallucination by changing the model’s job from generating facts from memory to reasoning over retrieved evidence. But search alone is not the solution. Reliable systems combine good retrieval, constrained outputs, and verification, making hallucination reduction an engineering discipline.
Why hallucination is a systems problem, not a model problem
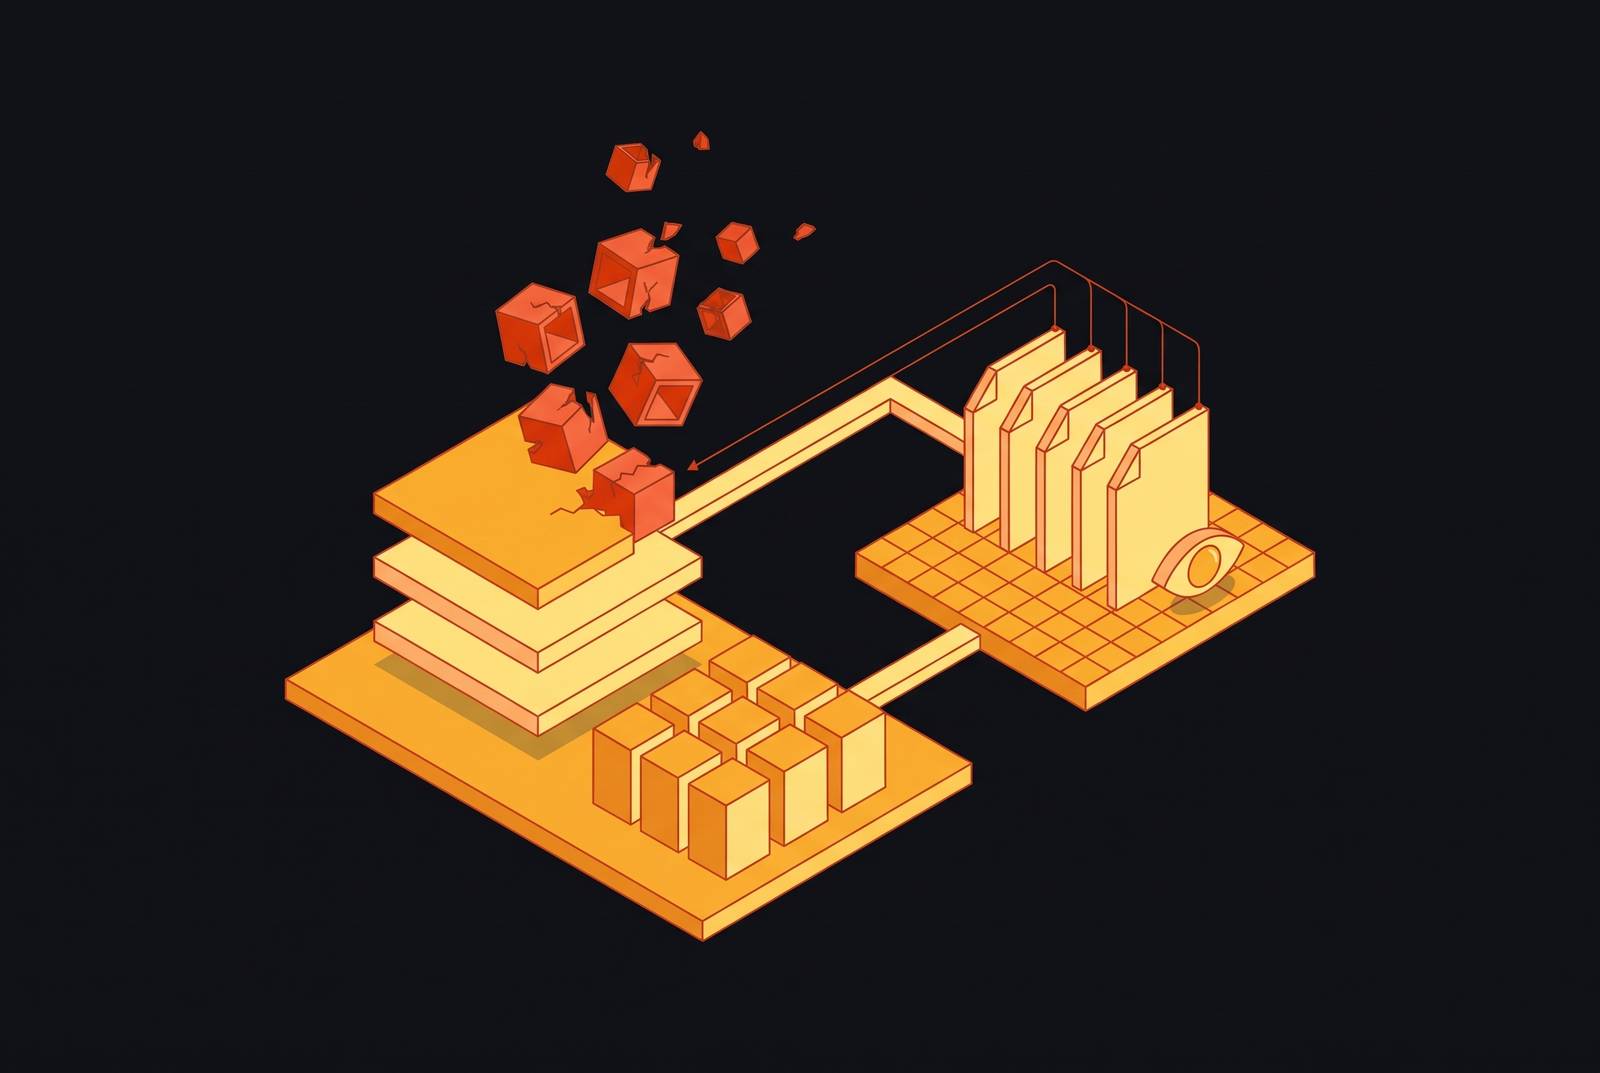
A production medical chatbot retrieved the correct chunk, ignored it, and fabricated a more impressive-sounding citation instead. No faithfulness judge caught the substitution. The evidence was present, but the pipeline failed. This case exposes the limit of treating hallucination as a knowledge deficit that more training or a larger model will resolve.
Next-token prediction favors continuations that sound plausible, whether or not they are true. When training data is sparse or a prompt is ambiguous, a confident wrong answer can be the probable continuation. Factuality failures contradict the real world, often because the model’s parametric memory lacks the fact. Faithfulness failures contradict supplied evidence, requiring a different intervention.
The distinction determines where engineering effort belongs. External grounding addresses missing knowledge, while runtime verification checks whether the model used that knowledge faithfully. Even correct context can lose its influence when buried in an oversized retrieved set. A larger model does not, by itself, remove either the incentive to produce fluent answers or the dilution of relevant evidence.
What hallucination rates actually look like across domains before any grounding is applied
Ungrounded reliability varies sharply with the task. Constrained summarization and open-ended factual questions ask different things of a model, so doing well at one says little about how well it will do at the other. Medical and legal tasks show especially serious weaknesses, with medical hallucination rates well above half when safeguards are absent. These are not marginal errors in otherwise dependable workflows.
What makes the variation useful for diagnosis? Limits in the data are a main cause of error, while probabilistic generation and training-data bias can also cause errors. Together, data-related causes account for much of the problem. Some newer reasoning models also hallucinate more than earlier versions, showing that deeper reasoning and stronger factual reliability do not necessarily advance together.
An invented reference gives an unsupported statement the appearance of having survived an evidence check. Even when the statement itself is correct, a fabricated source makes the answer unreliable as a research artifact. When accuracy matters, smooth writing alone cannot show that an ungrounded answer is ready to use.
Why grounding shifts the model's role and why that shift is what reduces hallucination
Instead of asking the model to generate an answer from parametric memory, the system asks it to find and synthesize an answer within retrieved documents. The model becomes a reasoning layer over evidence.
Freshness adds another reason for that separation. A static corpus can become stale, leaving it unable to resolve contradictions about facts that have changed. Live web search retrieves evidence at query time, so the system can answer questions about recent events and fields that change quickly. But evidence can be current without being authoritative, and even evidence that has both qualities can lead to an unfaithful summary.
The useful analogy is a brilliant employee with a memory problem who confidently invents details. A reference library gives that employee something dependable to consult, but a constrained answer form and a supervisor remain necessary. The employee’s memory remains unreliable. The surrounding system has been designed so that unsupported recollection is no longer the only basis for an answer.
The three-layer architecture that makes grounding reliable in production
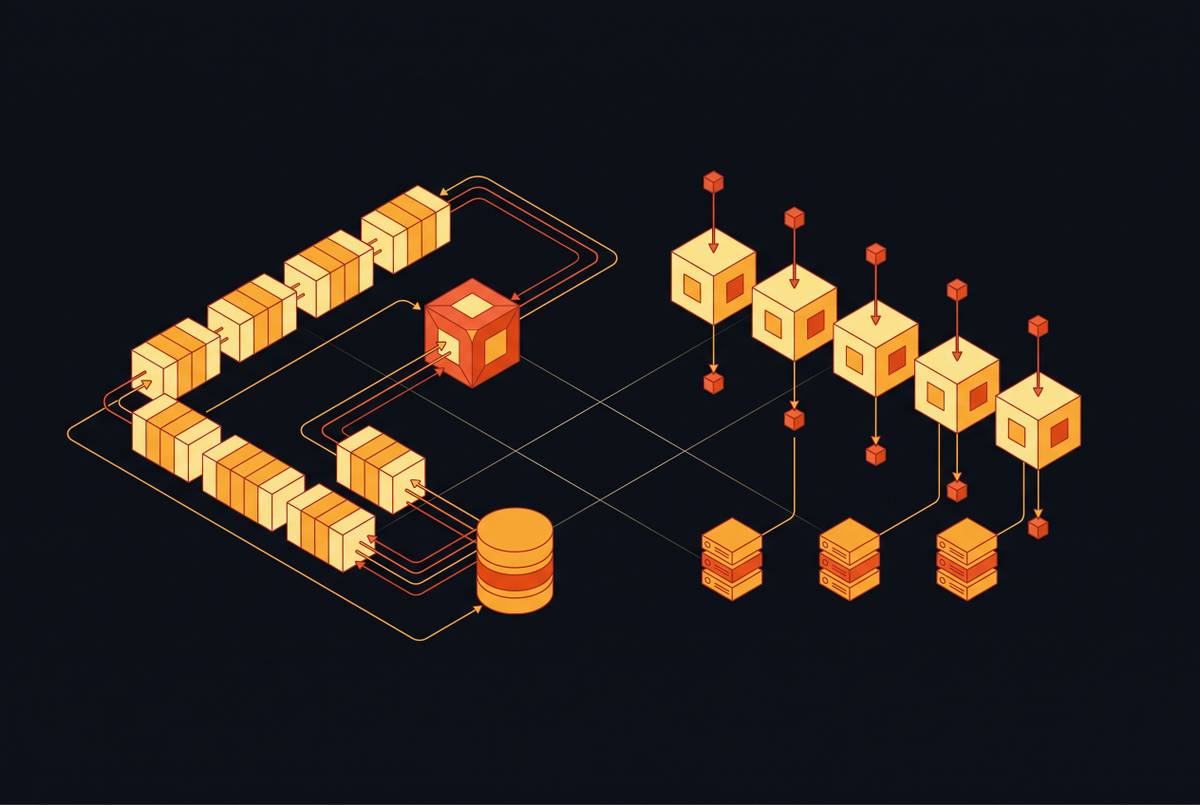
The first layer is retrieval quality control. Poor chunking or weak similarity matching sends the model context that does not fit the question, which it can turn into a confident but unsupported answer. Strict similarity thresholds, explicit top-k limits, and relevance ranking cut down on how much of that context reaches the model. Query rewriting improves the search request before retrieval, while hybrid retrieval combines BM25 keyword precision with dense embeddings for semantic relevance. A cross-encoder reranker then helps choose the evidence that best fits the question for the context.
The second layer constrains the output. A JSON schema with predefined fields can prevent invented fields and restrict the kinds of claims the model may express. This narrows the failure surface independently of retrieval quality. But a valid schema does not prove that the values inside it are true, so evidence checking is still needed alongside syntactic control.
The third layer verifies the generated answer before delivery. Runtime faithfulness judges compare claims with retrieved context, catching the medical chatbot’s failure to use evidence already available. Farquhar et al.’s 2024 Nature paper describes semantic uncertainty as another actionable signal, detected by sampling answers and measuring disagreement in meaning. These differences can flag confabulations without a knowledge source outside the system. When confidence is insufficient, abstention gates allow the system to withhold an answer.
Agentic RAG extends this architecture beyond a single retrieval pass. The generator can ask the retriever again and adapt its strategy to what the evidence has revealed so far, improving support for complex, multi-step questions. Verification therefore need not end only in acceptance or rejection. It can support another attempt to obtain adequate evidence. None of these layers requires a larger model or an architectural breakthrough, but each requires deliberate pipeline design.
How benchmarks reveal what grounding actually achieves — and where it still falls short
OpenAI’s vendor testing on FActScore reports a dramatic reduction in hallucination when a leading model receives web-search access. A substantial baseline falls to a very small fraction with browsing. That result supports the central mechanism of grounding, especially when questions are well formed and sources are clean. It does not establish how reliably the same approach handles conflicting evidence.
SealQA tests that harder condition directly. Its questions are designed so that web search yields conflicting, noisy, or unhelpful results, unlike the more curated questions associated with SimpleQA. Can the system recognize when retrieved material is insufficient or contradictory?
LiveNewsBench reports overall accuracy ranging from low double digits to 90% across models and frameworks. Search augmentation is plainly not a uniform capability. Because the comparison spans both models and frameworks, it makes infrastructure and integration quality impossible to ignore. Developers should try to reproduce vendor results themselves on workloads like their own, because scores from different question sets and evaluation harnesses can be poor guides to how a system will work in production.
What separates search infrastructure that reduces hallucination from search infrastructure that shifts it
For developers choosing a search API, the first question is what evidence the model will actually receive. Links alone do not answer it. Retrieval needs relevance and coverage across factual, technical, current-event, and research queries, with clean, full-page content that supports reasoning. Titles, snippets, stale pages, or stripped text can leave gaps that invite the model to supply what the source never said.
Provenance is the next requirement. URLs, domains, and date signals allow downstream checks to connect claims with their sources, while domain, date, and region filters help constrain retrieval. Wallat et al.’s 2024 RAG attribution study found post-rationalization in up to 57% of evaluated citations. A citation can support an answer yet still misrepresent how the model formed it. Per-claim tracing is therefore necessary to distinguish evidence use from an explanation attached afterward.
Low latency supports repeated retrieval, while tool-calling compatibility, stable schemas, and predictable failure handling keep search from disrupting the agent’s workflow. If each search adds seconds, an iterative grounding loop can become impractical. Rate limits and latency spikes consequently belong in the same evaluation as relevance.
Privacy imposes another constraint on the retrieval boundary. Agent queries can include personal data, account identifiers, or private details about a business, so the API is a data processor under GDPR and an input source under the EU AI Act. Zero data retention and SOC2 certification are baseline selection requirements in this framework. The quality of an answer cannot compensate for an unsuitable data-handling arrangement.
High-stakes domains where grounded architecture is already demonstrating production results
Morgan Stanley deployed an OpenAI GPT-4 system for wealth management advisory grounded in vetted internal research. The deployment reported a 90% reduction in research retrieval time. Wells Fargo deployed a RAG-based tool that retrieves policies and procedures during customer interactions, reducing workflow time for query resolution. These cases show how access to authoritative material can save time, though time saved alone does not measure every kind of hallucination.
FinGround provides a more direct test of verification in finance. The system, accepted to ACL 2026 Industry Track, compares pipelines receiving identical retrieval and reports sharply lower hallucination with structured verification than strong baselines. Holding retrieval constant is important here. It separates the gains from checking claims from the gains that might otherwise come from supplying better documents.
Healthcare offers a related example of traceability as a control. In the policy-grounding case, hallucination dropped to near-zero when every answer had to be traceable to a retrieved policy snippet. Palo Alto Networks likewise used Gemini for a grounded security-support assistant that drew on the organization’s data and security protocols to make its answers much more accurate.
CEO Sebastian Siemiatkowski acknowledged that aggressive AI-first workforce reduction had created quality issues in complex customer service interactions. The company said it would rebuild human expertise in selected areas while keeping AI as the main first point of contact. This shows why human judgment remains necessary when no retrieved document authoritatively resolves an edge case.
What the remaining hallucination rate tells developers about where to invest next
A residual hallucination is useful only if the system can locate its cause. When the right chunk was present but ignored, the next investigation concerns context placement, chunk size, and faithfulness-judge configuration. When sources were absent, noisy, or contradictory, retrieval coverage, query rewriting, and abstention become the relevant controls.
Citation misattribution requires its own diagnosis. Better search will not necessarily fix an answer that attaches a plausible source after forming its claim. Structured output enforcement and a misattribution-specific judge tackle that failure after retrieval. The three-layer architecture thus provides a map for instrumentation, rather than a general instruction to improve the model whenever an answer goes wrong.
An agent without persistent, sourced memory can recreate information gaps at the start of each conversation. A memory layer must therefore be source-cited and updatable.
For developers, the practical response is to instrument each failure mode, attach metrics to the relevant pipeline stage, and gate responses before delivery. Retrieval infrastructure remains a central investment because it determines which evidence the rest of the system can use. But its quality must be judged with verification and integration.